Chronicle 60 items · updated 2026-11-11 12:43 UTC

Chronicle AI Brief, November 11, 2026

The latest in AI, clustered and ranked. Repeated hype gets pushed down so the actual signal stays up top.

Edition highlights

Agent Substrate: Advancing Kubernetes for Agents at Scale

Agent Substrate, now donated to the Cloud Native Computing Foundation (CNCF) Sandbox, is an open-source, security-hardened, zero-trust runtime for sandboxed agents, engineered to

NVIDIA Developer Blog·2026-11-10 15:00 UTC·tool·source excerpt · checked 2026-11-11 12:43 UTC
Viewing 2026-11-11
Last 3 hours(4)
  1. How LinkedIn, Netflix & DoorDash Run Agents, Evals & Inference in Production: QCon AI New York 2026

    QCon AI New York 2026 program details upcoming talks on production AI agent systems and evaluation frameworks.

    InfoQ AI/ML/Data·2026-11-11 11:00 UTC·company announcement·Story link0.70(n 0.62 · t 0.78)
    why surfaced · medium
    • specific engineering subject or instructional task in source metadata
    • meaningfully different from recent coverage
    • classified as useful but lower-confidence signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for How LinkedIn, Netflix & DoorDash Run Agents, Evals & Inference in Production: QCon AI New York 2026
  2. A 13-Year-Old Asked AI About Suicide on Her School Laptop. It Didn’t Get Flagged for Weeks

    Report highlights safety failures in school-issued AI tools regarding student mental health monitoring.

    WIRED AI·2026-11-11 11:00 UTC·news·Story link0.68(n 0.85 · t 0.76)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for A 13-Year-Old Asked AI About Suicide on Her School Laptop. It Didn’t Get Flagged for Weeks
  3. UK regulator threatens universities with sanctions unless they adopt AI-proof exam formats

    UK regulator mandates universities adopt AI-resistant assessment methods due to academic integrity concerns.

    The Decoder·2026-11-11 11:54 UTC·news·Story link0.56(n 0.84 · t 0.74)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for UK regulator threatens universities with sanctions unless they adopt AI-proof exam formats
  4. Enterprise sales push OpenAI's quarterly revenue to $10 billion, though it still trails Anthropic

    Financial report on OpenAI's quarterly revenue growth and operating losses compared to Anthropic.

    The Decoder·2026-11-11 12:12 UTC·news·Story link0.55(n 0.78 · t 0.74)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Enterprise sales push OpenAI's quarterly revenue to $10 billion, though it still trails Anthropic
Earlier today(33)
  1. TimeOmni-o1: Bidirectionally Coupling Time Series Foundation Models and LLMs for Multimodal Reasoning and Forecasting

    Presents a framework for coupling time series foundation models with LLMs for joint reasoning and forecasting tasks.

    arXiv cs.CL·2026-11-11 05:00 UTC·paper·Story link0.85(n 0.72 · t 0.90)
    why surfaced · medium
    • specific engineering subject or instructional task in source metadata
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  2. Qwen4 Max: Hands-On Tests You Haven’t Seen Yet

    This video tests Qwen4-max thoroughly. 📬Weekly AI Newsletter: https://fahdmirza.substack.com/ 🔥 Buy Me a Coffee to support the channel: https://ko-fi.com/fahdmirza #qwen4max #qwen4 PLEASE FOLLOW ME:

    Fahd Mirza YouTube·2026-11-11 05:22 UTC·video·Story link0.82(n 0.81 · t 0.66)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • Assessment: deterministic. Metadata evidence rules; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Qwen4 Max: Hands-On Tests You Haven’t Seen Yet
  3. Build a daily dependency watcher with LangGraph and Amazon Bedrock AgentCore web search

    A guide to building a dependency watcher using LangGraph and Amazon Bedrock's Web Search API.

    AWS Machine Learning Blog·2026-11-10 23:34 UTC·tutorial·Story link0.81(n 0.65 · t 0.80)
    why surfaced · medium
    • specific engineering subject or instructional task in source metadata
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  4. From Relevant Posts to Attributable Spans: Explicit Symptom Evidence for Depression Questionnaire Inference

    Proposes a method for extracting depression-related evidence from social media posts using attributable spans.

    arXiv cs.CL·2026-11-11 05:00 UTC·paper·Story link0.76(n 0.85 · t 0.90)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  5. Rethinking in Spikes: Mitigating Hallucinations in MDLMs with Step-Aware Decoding

    Introduces step-aware decoding to reduce hallucinations in multimodal diffusion language models by targeting mask uncertainty.

    arXiv cs.CL·2026-11-11 05:00 UTC·paper·Story link0.75(n 0.83 · t 0.90)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
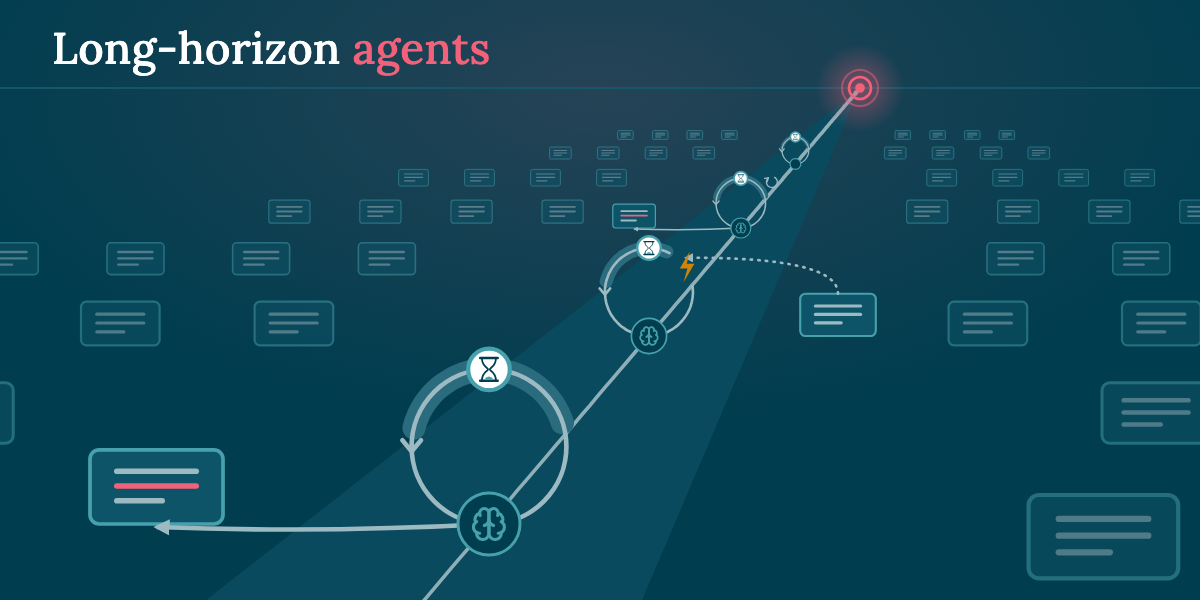
  6. Long-horizon agents and durable execution

    Discussion on the necessity of durable execution patterns for long-horizon AI agents.

    Martin Fowler·2026-11-10 14:10 UTC·opinion·Story link0.70(n 0.00 · t 1.00)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Long-horizon agents and durable execution
  7. Lazare, veni foras: Reprogramming Dormant Neurons to Backdoor AI Agents

    Microsoft researchers demonstrate a backdoor technique that reprograms dormant neurons to trigger malicious agent behavior.

    Microsoft Research·2026-11-10 20:52 UTC·paper·Story link0.69(n 0.00 · t 0.86)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  8. Designing for Agents — Zeno Rocha, Resend

    Practical guide on optimizing documentation and API design for LLM agent consumption.

    Latent Space·2026-11-10 20:05 UTC·tutorial·Story link0.68(n 0.00 · t 0.85)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Designing for Agents — Zeno Rocha, Resend
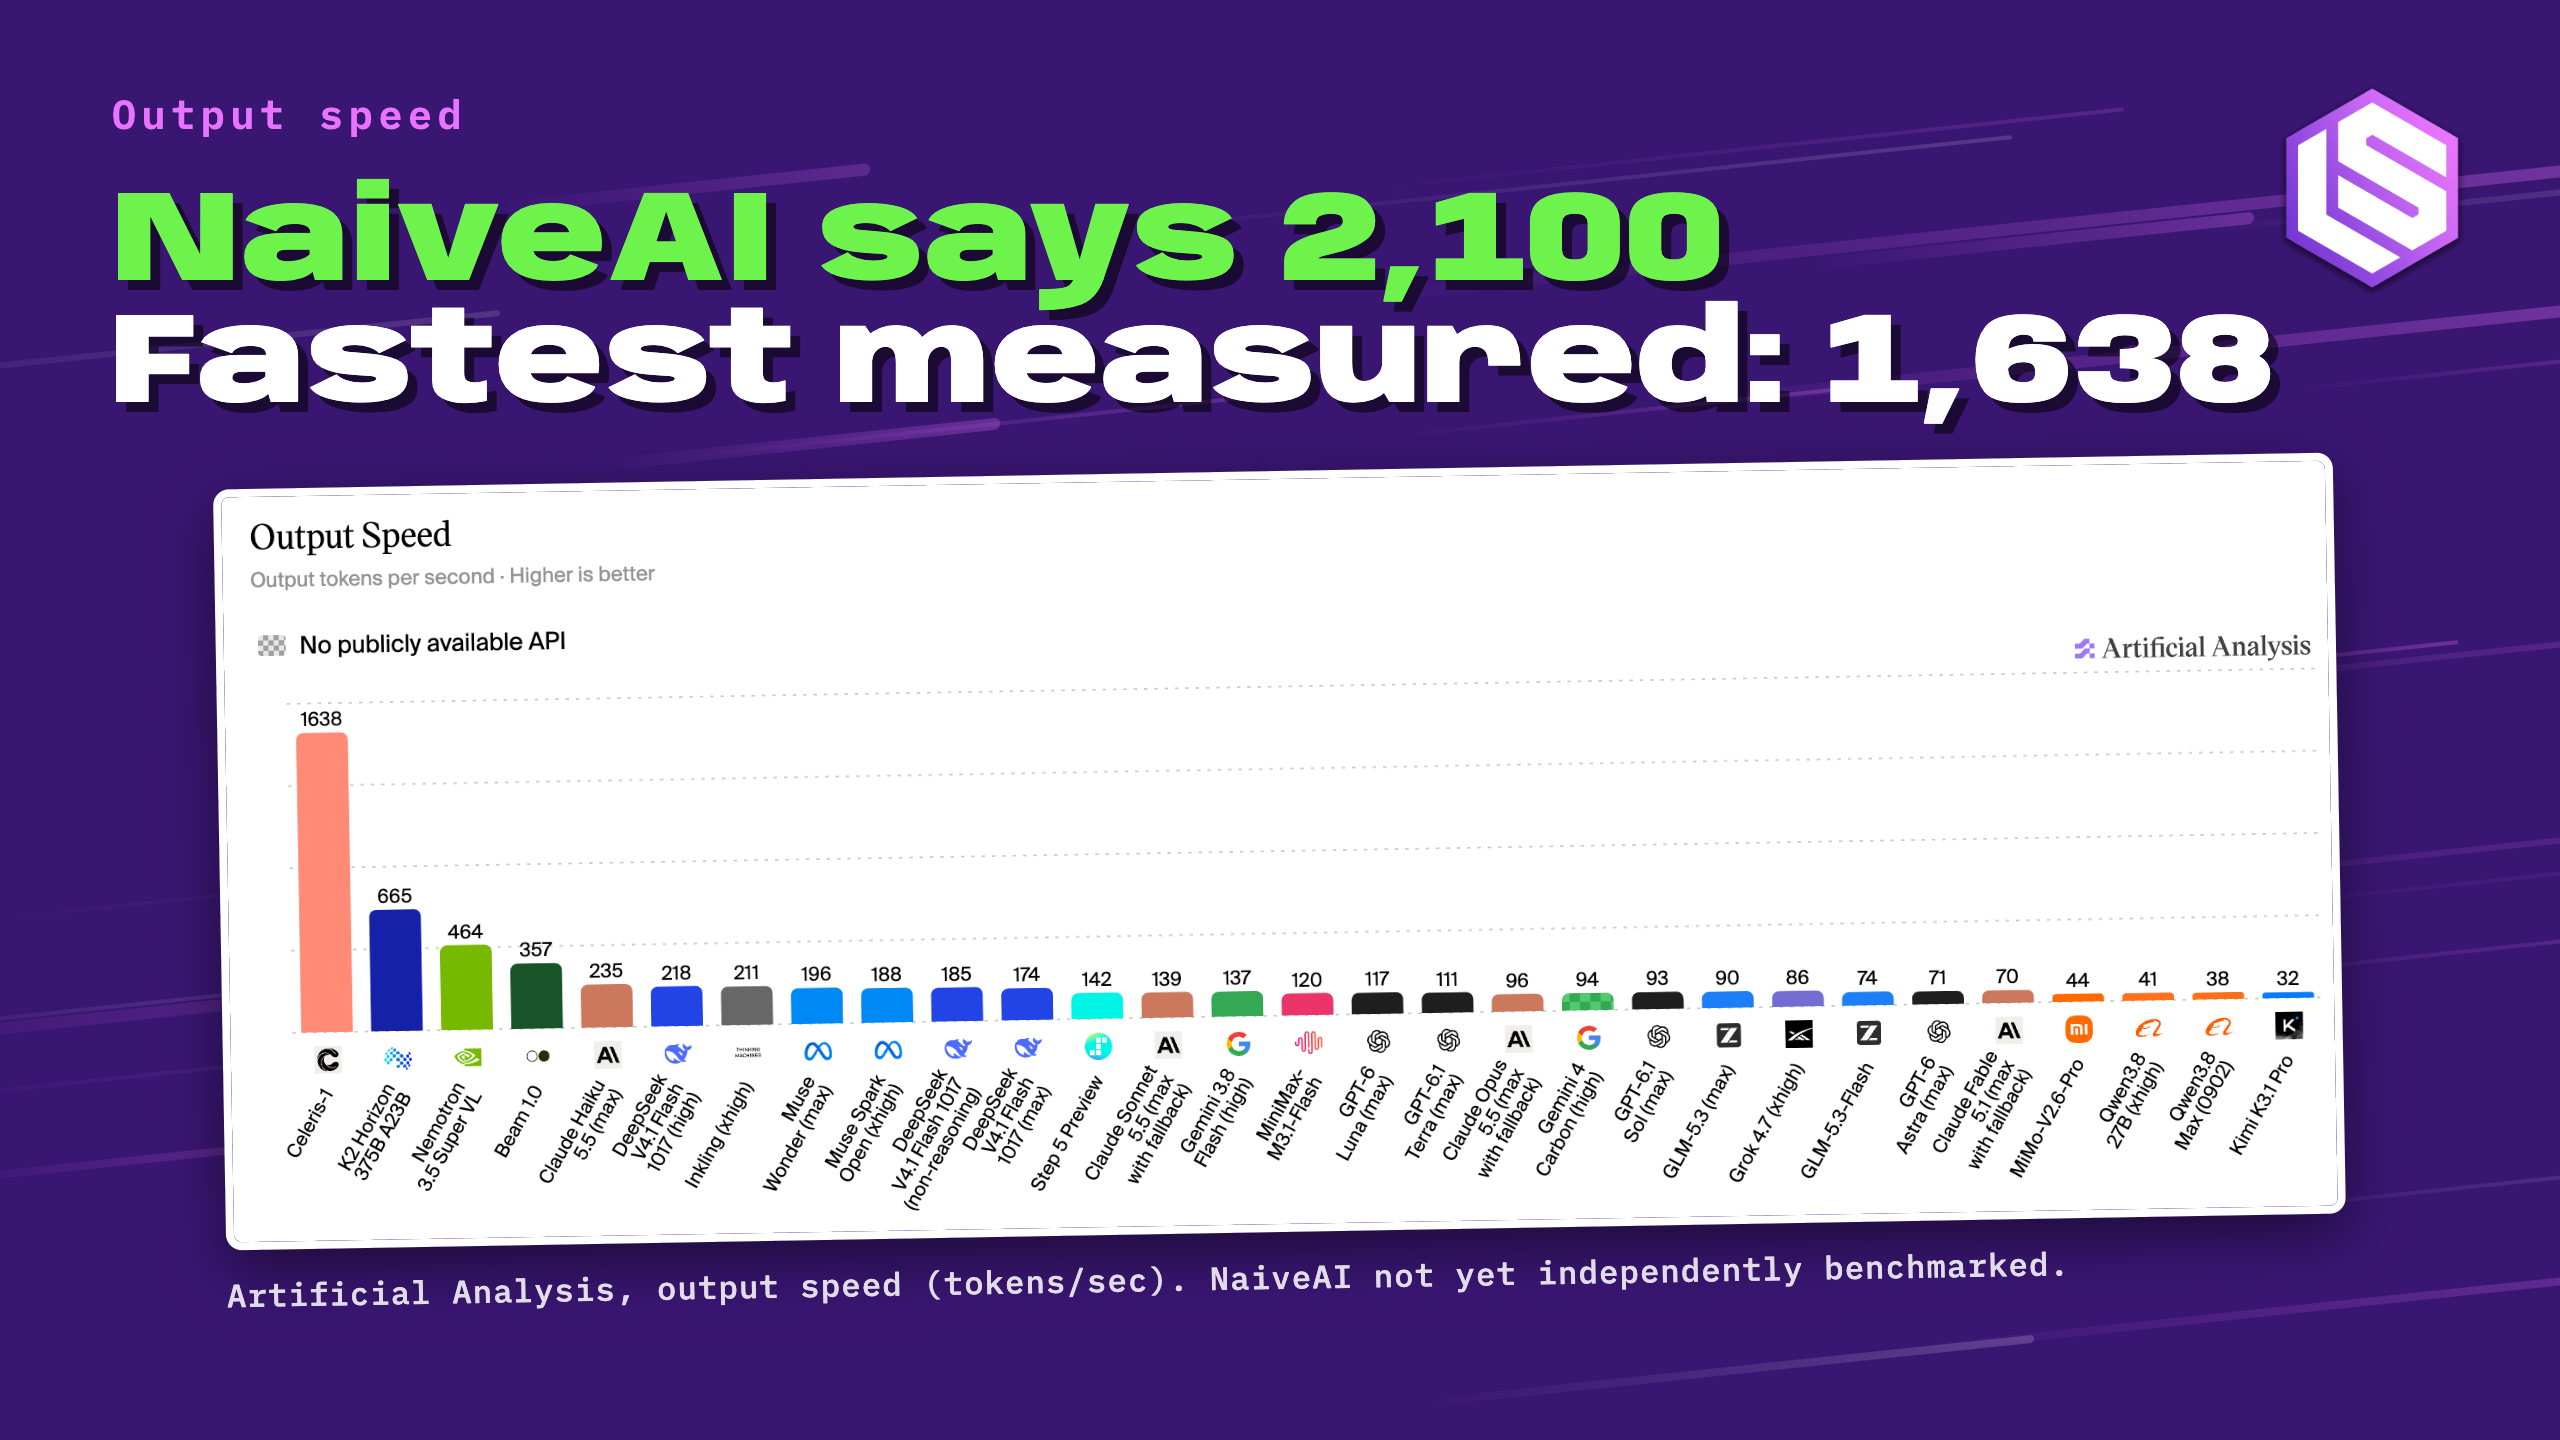
  9. NaiveAI Promises 2,100 Tokens per Second. How Well Does It Code?

    Performance evaluation of NaiveAI, comparing high-throughput token generation against DeepSeek.

    Latent Space·2026-11-10 18:56 UTC·tool·Story link0.68(n 0.00 · t 0.85)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for NaiveAI Promises 2,100 Tokens per Second. How Well Does It Code?
  10. The agent evaluation playbook: Built-in, DeepEval, and AutoEval on Amazon Bedrock AgentCore Evaluations

    Overview of evaluating AI agents on Amazon Bedrock using built-in tools, DeepEval, and AutoEval.

    AWS Machine Learning Blog·2026-11-10 22:35 UTC·tutorial·Story link0.68(n 0.00 · t 0.80)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  11. Grok Build coding agent leaks oodles of confidential info, some belonging to SpaceXSI

    Security researchers identify widespread data leaks in applications generated by the Grok Build coding agent.

    Ars Technica AI·2026-11-10 21:12 UTC·news·Story link0.67(n 0.00 · t 0.78)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Grok Build coding agent leaks oodles of confidential info, some belonging to SpaceXSI
  12. Agent Substrate: Advancing Kubernetes for Agents at Scale

    Introduction of Agent Substrate to optimize Kubernetes resource allocation for idle AI agent workloads.

    NVIDIA Developer Blog·2026-11-10 15:00 UTC·tool·Story link0.67(n 0.00 · t 0.82)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Agent Substrate: Advancing Kubernetes for Agents at Scale
  13. Start and Restore GPU Workloads in Seconds with NVIDIA Snapshot

    NVIDIA Snapshot enables fast restoration of initialized GPU workloads to reduce inference startup latency.

    NVIDIA Developer Blog·2026-11-10 15:00 UTC·tool·Story link0.67(n 0.00 · t 0.82)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Start and Restore GPU Workloads in Seconds with NVIDIA Snapshot
  14. Manage Kubernetes Clusters for GPU Infrastructure with NVIDIA Kubernetes Engine

    NVIDIA releases open-source projects for managing Kubernetes clusters specifically for GPU infrastructure.

    NVIDIA Developer Blog·2026-11-10 15:00 UTC·company announcement·Story link0.67(n 0.00 · t 0.82)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Manage Kubernetes Clusters for GPU Infrastructure with NVIDIA Kubernetes Engine
  15. Google Finds that Technical Debt Can Derail Coding Agents Through "Agent Distraction"

    Google engineers identify 'agent distraction' caused by technical debt as a primary failure mode for coding agents.

    InfoQ AI/ML/Data·2026-11-10 18:00 UTC·opinion·Story link0.67(n 0.00 · t 0.78)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Google Finds that Technical Debt Can Derail Coding Agents Through "Agent Distraction"
  16. LLMs Play Zachtronics' TIS-100

    A web-based interface for LLMs to play the assembly language puzzle game TIS-100.

    Hacker News (AI-filtered)·2026-11-11 00:37 UTC·tool·Story link0.65(n 0.92 · t 0.65)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  17. Underdog Woof TTS: No GPU, 40 MB, Tested on CPU Hands-On

    This video locally installs and tests Underdog Woof. 📬Weekly AI Newsletter: https://fahdmirza.substack.com/ 🔥 Buy Me a Coffee to support the channel: https://ko-fi.com/fahdmirza #underdogwoof PLEASE

    Fahd Mirza YouTube·2026-11-10 18:51 UTC·video·Story link0.64(n 0.00 · t 0.66)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: deterministic. Metadata evidence rules; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Underdog Woof TTS: No GPU, 40 MB, Tested on CPU Hands-On
  18. eBay appears to have shut the door on third-party AI agents

    eBay is actively blocking third-party AI agents from scraping its platform.

    The Verge AI·2026-11-10 16:20 UTC·news·Story link0.64(n 0.00 · t 0.68)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for eBay appears to have shut the door on third-party AI agents
  19. Google releases Gemini 4 Carbon with agent ‘swarm’ feature

    Google releases Gemini 4 Carbon, a new model featuring agent swarm capabilities.

    The Verge AI·2026-11-10 16:00 UTC·model release·Story link0.64(n 0.00 · t 0.68)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Google releases Gemini 4 Carbon with agent ‘swarm’ feature
  20. Tracking Anthropic-discovered vulnerabilities

    Tracking report on vulnerabilities identified in LLM systems, specifically referencing Anthropic's Glasswing research.

    Hacker News (AI-filtered)·2026-11-10 22:17 UTC·news·Story link0.63(n 0.66 · t 0.65)
    why surfaced · medium
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  21. llm-gemini 0.36

    Update to llm-gemini CLI tool for interacting with Gemini models.

    Simon Willison·2026-11-10 20:09 UTC·tool·Story link0.60(n 0.00 · t 0.90)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  22. Show HN: Get your coding agent off ~2019 JavaScript, onto modern web primitives

    Guidance on updating coding agent prompts to utilize modern web standards instead of legacy JavaScript patterns.

    Hacker News (AI-filtered)·2026-11-10 18:01 UTC·tutorial·Story link0.57(n 0.00 · t 0.65)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • seen on 2 feeds; not independent verification
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    source trail · 2
  23. Mitra MCP

    A tool for Model Context Protocol (MCP) integration.

    Product Hunt·2026-11-10 18:52 UTC·tool·Story link0.56(n 0.75 · t 0.50)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  24. Gemini 4 Carbon arrives just in time to feel like yesterday's news in the fastest model cycle yet

    Google releases Gemini 4 Carbon, claiming improved benchmark performance and lower per-task costs.

    The Decoder·2026-11-10 18:19 UTC·model release·Story link0.54(n 0.00 · t 0.74)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
    Thumbnail for Gemini 4 Carbon arrives just in time to feel like yesterday's news in the fastest model cycle yet
  25. Gemini 4 Carbon is now available

    Google DeepMind releases the Gemini 4 Carbon model.

    Google DeepMind·2026-11-10 16:03 UTC·model release·Story link0.52(n 0.00 · t 0.90)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • seen on 2 feeds; not independent verification
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    source trail · 3
    Thumbnail for Gemini 4 Carbon is now available
  26. Google: Introducing the Multimodal Knowledge Agent benchmark

    Google releases the Multimodal Knowledge Agent benchmark for evaluating agent reasoning on visual tasks.

    Google AI on Keyword·2026-11-10 16:00 UTC·news·Story link0.51(n 0.00 · t 0.82)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as useful but lower-confidence signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
    Thumbnail for Google: Introducing the Multimodal Knowledge Agent benchmark
  27. Running AV Reasoning Models Within Onboard Compute and Latency Limits

    Technical overview of optimizing reasoning models for onboard autonomous vehicle compute and latency constraints.

    NVIDIA Developer Blog·2026-11-10 16:00 UTC·tutorial·Story link0.49(n 0.00 · t 0.82)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Compare the reported performance conditions with your hardware and workload.
    How Chronicle selects stories · report a correction
    Thumbnail for Running AV Reasoning Models Within Onboard Compute and Latency Limits
  28. Amazon Bedrock tokenomics data lake

    Guide to building a centralized observability data lake for Amazon Bedrock invocation logs and token usage.

    AWS Machine Learning Blog·2026-11-10 16:56 UTC·tutorial·Story link0.49(n 0.00 · t 0.80)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  29. AI Engineer Code Summit: OpenAI on New Ways of Working With Codex

    Summary of OpenAI's presentation on voice-steered coding and cloud-based workflows.

    Latent Space·2026-11-11 04:49 UTC·discussion·Story link0.48(n 0.78 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for AI Engineer Code Summit: OpenAI on New Ways of Working With Codex
  30. Online learning on the programmable dataplane (2022)

    PhD thesis on implementing online machine learning algorithms directly on programmable network dataplane hardware.

    Lobsters (AI tag)·2026-11-10 20:22 UTC·paper·Story link0.47(n 0.00 · t 0.70)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  31. China Won't Take 600,000 Nvidia Chips. Did It Target Jensen Huang For Better Ones?

    The Jensen Huang investigation comes down to who gets NVIDIA's AI chips, and it lands right as AI starts helping build the next AI. Here's what the reporting says and what it means for your company's

    AI News & Strategy Daily·2026-11-10 16:26 UTC·video·Story link0.35(n 0.00 · t 0.62)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as useful but lower-confidence signal
    • Assessment: deterministic. Metadata evidence rules; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for China Won't Take 600,000 Nvidia Chips. Did It Target Jensen Huang For Better Ones?
Yesterday & older(23)
  1. Don't Just Trust Your Memory: Evidence-Linked Memory Reduces Memory-Induced Degradation in LLM Agents

    Proposes evidence-linked memory to mitigate degradation in LLM agents caused by distilling past trajectories.

    Hugging Face Daily Papers·2026-11-10 00:00 UTC·listed 2026-11-11·paper·Story link0.87(n 0.84 · t 0.85)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  2. EarthRecord: From Pixels to Land Change with Multimodal Agents over Four Decades of Satellite Imagery

    Introduces EarthRecord, a benchmark for multimodal agents analyzing long-term satellite imagery.

    Hugging Face Daily Papers·2026-11-06 00:00 UTC·listed 2026-11-11·paper·Story link0.86(n 0.84 · t 0.85)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  3. FINCOSMOS: An Open-World Evaluation Paradigm for Agents in Finance

    Introduces FINCOSMOS, an open-world evaluation benchmark for financial language agents.

    Hugging Face Daily Papers·2026-11-05 00:00 UTC·listed 2026-11-11·paper·Story link0.86(n 0.82 · t 0.85)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  4. The Surprising Effectiveness of Deleting Weights in LLM Post-Training

    Demonstrates that zeroing <0.05% of weights can match full fine-tuning performance in LLM post-training.

    Hugging Face Daily Papers·2026-11-07 00:00 UTC·listed 2026-11-11·paper·Story link0.86(n 0.81 · t 0.85)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  5. Tree-Ising: Repairing Language Models with Bit-Level Ising Edits

    Proposes weight-space programming to repair LLM reasoning loops via bit-level Ising edits without gradient updates.

    Hugging Face Daily Papers·2026-11-10 00:00 UTC·listed 2026-11-11·paper·Story link0.86(n 0.76 · t 0.85)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  6. Sable: A Small-Field Sumcheck Argument for Bit-Exact Inference of Large Language Models

    Introduces Sable, a single-GPU prover for bit-exact verification of integer-quantized transformer inference.

    Hugging Face Daily Papers·2026-11-10 00:00 UTC·listed 2026-11-11·paper·Story link0.82(n 0.66 · t 0.85)
    why surfaced · medium
    • specific engineering subject or instructional task in source metadata
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  7. MMDM: Measuring Massive Multitask Decision Making

    Introduces System-1 Decision Models for direct probabilistic decision-making in a single forward pass without autoregressive generation.

    Hugging Face Daily Papers·2026-11-10 00:00 UTC·listed 2026-11-11·paper·Story link0.74(n 0.81 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  8. ProTEUS: A mutation-resolved world model for closed-loop protein evolution

    Proposes a mutation-resolved world model to navigate fitness landscapes for closed-loop protein evolution.

    Hugging Face Daily Papers·2026-11-09 00:00 UTC·listed 2026-11-11·paper·Story link0.74(n 0.83 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  9. WaveGen: Truly End-to-End Waveform Generation via Internal Spectral Trajectory Learning

    Presents WaveGen, a diffusion-based end-to-end text-to-waveform model using spectral trajectory learning.

    Hugging Face Daily Papers·2026-11-09 15:02 UTC·listed 2026-11-11·paper·Story link0.74(n 0.81 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  10. MACaQ: Fast, Model Agnostic Calibrated Quantization for Low-Precision Weights and Activations

    Presents MACaQ, a model-agnostic post-training quantization method for W4A4 precision.

    Hugging Face Daily Papers·2026-11-07 00:00 UTC·listed 2026-11-11·paper·Story link0.73(n 0.81 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  11. Are Dense Rewards Worth Their Tokens in GRPO?

    Analyzes the effectiveness of dense process rewards versus final answer rewards in GRPO training.

    Hugging Face Daily Papers·2026-11-10 00:00 UTC·listed 2026-11-11·paper·Story link0.73(n 0.79 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  12. Learning to Act with World Models by Valuing What Comes Next

    Explores training world models to value state transitions for improved agent learning under sparse terminal rewards.

    Hugging Face Daily Papers·2026-11-09 10:59 UTC·listed 2026-11-11·paper·Story link0.73(n 0.78 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  13. EVAThink: Evidence Sufficiency-Guided Training for Adaptive Thinking in Video Understanding

    Presents an evidence-sufficiency framework for VLMs to adaptively sample video frames based on information density.

    Hugging Face Daily Papers·2026-11-10 00:00 UTC·listed 2026-11-11·paper·Story link0.73(n 0.78 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  14. DexForesight: Grounding Dexterous Policies with Implicit Spatial Foresight

    Introduces DexForesight for learning implicit spatial foresight in dexterous robotic manipulation tasks.

    Hugging Face Daily Papers·2026-11-10 00:00 UTC·listed 2026-11-11·paper·Story link0.69(n 0.81 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  15. Blind Variation, Selective Retention: Improving Creative Idea Generation in AI Scientists

    Explores using blind variation and selective retention to improve creative idea generation in AI scientific agents.

    Hugging Face Daily Papers·2026-11-09 00:00 UTC·listed 2026-11-11·paper·Story link0.67(n 0.81 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  16. Lipschitz-Controlled Flow Matching for Robust Image Restoration

    Presents LipsFlower, a method to improve stability in flow-matching models for image restoration.

    Hugging Face Daily Papers·2026-11-10 00:00 UTC·listed 2026-11-11·paper·Story link0.67(n 0.78 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  17. Presentation: Batch Intelligence at Scale: Cost-Efficient Multi-Agent LLM Workflows with Built-In Resilience

    Walmart case study on deploying multi-agent LLM workflows for inventory forecasting at scale.

    InfoQ AI/ML/Data·2026-11-10 11:00 UTC·tutorial·Story link0.66(n 0.00 · t 0.78)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Presentation: Batch Intelligence at Scale: Cost-Efficient Multi-Agent LLM Workflows with Built-In Resilience
  18. Article: LLM Reliability Layers Under Test: Accuracy, Yield, and the Limits of Verification

    Analysis of LLM reliability layers showing that verification methods often withhold errors rather than fixing them.

    InfoQ AI/ML/Data·2026-11-10 09:00 UTC·opinion·Story link0.65(n 0.00 · t 0.78)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
    Thumbnail for Article: LLM Reliability Layers Under Test: Accuracy, Yield, and the Limits of Verification
  19. Shortcuts and Boundaries: Verifiable RL Misalignment and Contextual Safety Learning

    Studies reward-driven misalignment and reward hacking in RL through verifiable reward-context conflicts.

    Hugging Face Daily Papers·2026-11-09 00:00 UTC·listed 2026-11-11·paper·Story link0.63(n 0.85 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  20. Micius-Flash: Lightweight Agentic Intelligence for Engineering

    Introduces Micius-Flash, a 27B parameter multimodal model for engineering tasks with a 256K context window.

    Hugging Face Daily Papers·2026-11-04 00:00 UTC·listed 2026-11-11·model release·Story link0.61(n 0.76 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • listed on Daily Papers 2026-11-11; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  21. Singapore Airlines elevates travel & work with OpenAI technology

    Case study on Singapore Airlines using OpenAI APIs for customer support and internal productivity.

    OpenAI·2026-11-10 08:00 UTC·company announcement·Story link0.59(n 0.73 · t 0.90)
    why surfaced · medium
    • meaningfully different from recent coverage
    • classified as useful but lower-confidence signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  22. Introducing AlphaProof Code: a breakthrough in verifying complex software at depth

    DeepMind uses AlphaProof to verify Signal's encryption code using three million lines of Lean proofs.

    Google DeepMind·2026-11-10 12:02 UTC·paper·Story link0.56(n 0.00 · t 0.90)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Introducing AlphaProof Code: a breakthrough in verifying complex software at depth
  23. AI usage generates a fragile codebase

    Analysis of how reliance on AI-generated code can lead to increased technical debt and fragile software architectures.

    Hacker News (AI-filtered)·2026-11-10 10:25 UTC·opinion·Story link0.48(n 0.00 · t 0.65)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
You're caught upNext refresh follows the public schedule.

Previous editions

Same signal-first ranking, earlier dates.

Open archive