Chronicle 60 items · updated 2026-11-04 23:39 UTC · 2 sources skipped

Chronicle AI Brief, November 4, 2026

The latest in AI, clustered and ranked. Repeated hype gets pushed down so the actual signal stays up top.

Top News

Adversarial Speculative Reasoning Improves Long Horizon Agents

> Abstract:Speculative decoding has been treated purely as a systems optimization that speeds up large language model decoding without changing the model behavior. Under this

Hugging Face Daily Papers·2026-11-03 00:00 UTC·paper·source excerpt · checked 2026-11-04 23:39 UTC

Almost no one uses AI agents to book their Uber, company says

Very few people are using personal AI agents to order Ubers, apparently. On the transportation giant’s [third-quarter earnings](https://investor.uber.com/news-events/default.aspx)

TechCrunch AI·2026-11-04 21:56 UTC·news·source excerpt · checked 2026-11-04 23:39 UTC

Progress on provable inference for large language models

Specifically, we have made progress on a powerful type of cryptographic proof known as a “zkSNARK”, which is uniquely fit for **provable inference** (owing to

Hacker News (AI-filtered)·2026-11-04 17:17 UTC·paper·source excerpt · checked 2026-11-04 23:39 UTC

datasette-agent 0.5a0

This is a significant release of [Datasette Agent](https://agent.datasette.io/). The most notable new feature is called the **panel** - it lets the agent chat open and

Simon Willison·2026-11-03 23:13 UTC·tool·source excerpt · checked 2026-11-04 23:39 UTC
Viewing 2026-11-04
Last 3 hours(2)
  1. Almost no one uses AI agents to book their Uber, company says

    Uber reports extremely low adoption rates for AI agent-based ride booking.

    TechCrunch AI·2026-11-04 21:56 UTC·news0.83(n 0.78 · t 0.72)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  2. Meta acquires AI coding startup Conductor

    Meta acquires Conductor, a startup focused on multi-agent software engineering workflows.

    TechCrunch AI·2026-11-04 21:10 UTC·news0.64(n 0.83 · t 0.72)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
Earlier today(36)
  1. Use NVIDIA NeMo to Turn Agent Failures into Tests and Harness Fixes

    Workflow for converting agent production failures into automated tests using NVIDIA NeMo.

    NVIDIA Developer Blog·2026-11-04 16:00 UTC·tutorial0.85(n 0.79 · t 0.82)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
    Thumbnail for Use NVIDIA NeMo to Turn Agent Failures into Tests and Harness Fixes
  2. Four layers of context engineering for production AI agents: How Deep Insight applies them in working code

    Framework for context engineering in production agents, covering architecture, prompts, tools, and verification.

    AWS Machine Learning Blog·2026-11-04 16:30 UTC·tutorial0.83(n 0.73 · t 0.80)
    why surfaced · medium
    • specific engineering subject or instructional task in source metadata
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  3. Uber only fulfilled 4 rides from AI agents last quarter

    Uber reports minimal adoption of third-party AI agents for ride-hailing services in Q3 2026.

    The Verge AI·2026-11-04 15:58 UTC·news0.82(n 0.81 · t 0.68)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Uber only fulfilled 4 rides from AI agents last quarter
  4. Together Compiler: Continual Compilation for AI inference

    Together AI released a compiler using agents to optimize open model inference throughput dynamically.

    Together AI·2026-11-04 00:00 UTC·tool0.82(n 0.79 · t 0.80)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Compare the reported performance conditions with your hardware and workload.
    How Chronicle selects stories · report a correction
  5. Progress on provable inference for large language models

    Anthropic research on formal verification methods for improving reliability and provability of LLM inference.

    Hacker News (AI-filtered)·2026-11-04 17:17 UTC·paper0.74(n 0.75 · t 0.65)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  6. Ripple-65B Preview: U.S. Open-Weight SOTA on Agentic Coding

    Ripple-65B model release targeting agentic coding tasks.

    Hacker News (AI-filtered)·2026-11-04 18:53 UTC·model release0.74(n 0.73 · t 0.65)
    why surfaced · medium
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  7. How NVIDIA Factory Operations Blueprint Coordinates AI Agents to Investigate Production Issues

    NVIDIA blueprint for coordinating AI agents to investigate industrial production issues.

    NVIDIA Developer Blog·2026-11-04 17:00 UTC·tool0.73(n 0.78 · t 0.82)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for How NVIDIA Factory Operations Blueprint Coordinates AI Agents to Investigate Production Issues
  8. New open-source benchmark reveals reasoning as the biggest bottleneck for AI in cloud operations

    CloudOpsBench is a new open-source benchmark for evaluating AI agent performance on cloud DevOps tasks.
    The Decoder·2026-11-04 16:42 UTC·paper0.71(n 0.80 · t 0.74)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
    Thumbnail for New open-source benchmark reveals reasoning as the biggest bottleneck for AI in cloud operations
  9. Polymorphic Inference: self-tuning inference for open models

    Together AI announces a self-tuning inference framework for adapting models to changing hardware and traffic.

    Together AI·2026-11-04 00:00 UTC·company announcement0.71(n 0.80 · t 0.80)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  10. A Conditional Mutual Information Analysis of Response Variety in Language Models

    Uses conditional mutual information to quantify and analyze response variety in LLMs.

    arXiv cs.CL·2026-11-04 05:00 UTC·paper0.69(n 0.00 · t 0.90)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  11. A thousand fewer paths to root

    Report on an autonomous pipeline that identified and patched 948 Linux kernel privilege-escalation vulnerabilities.

    OpenAI·2026-11-04 08:00 UTC·paper0.69(n 0.88 · t 0.90)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  12. Why Pay for Long Reasoning When Rewrite Do Trick? Causal Effects of Reasoning History Compaction on Future Generation and Agent Cost

    Analyzes the cost-benefit of compacting reasoning traces in LLMs to reduce inference costs.

    arXiv cs.CL·2026-11-04 05:00 UTC·paper0.69(n 0.00 · t 0.90)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  13. Use decision models with Amazon Bedrock AgentCore Evaluations

    Guide on integrating external decision models into Amazon Bedrock AgentCore for structured evaluation.

    AWS Machine Learning Blog·2026-11-04 18:46 UTC·tutorial0.68(n 0.55 · t 0.80)
    why surfaced · medium
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  14. Anthropic's text watermark is easy to bypass on several older Claude models

    Anthropic's text watermarking on older Claude models can be bypassed by modifying sampling parameters.

    The Decoder·2026-11-04 19:03 UTC·news0.68(n 0.61 · t 0.74)
    why surfaced · medium
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Anthropic's text watermark is easy to bypass on several older Claude models
  15. Qualcomm Cloud AI 100 Ultra – 150W AI Accelerator Card with 128GB at 548GB/s

    Qualcomm releases Cloud AI 100 Ultra accelerator with 128GB memory and 548GB/s bandwidth.

    Hacker News (AI-filtered)·2026-11-04 19:55 UTC·news0.67(n 0.86 · t 0.65)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • fresh within the current refresh window
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  16. datasette-llm 0.1a10

    Datasette-llm plugin update for integrating LLM capabilities into Datasette.

    Simon Willison·2026-11-04 15:26 UTC·tool0.67(n 0.28 · t 0.90)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  17. GPT-6 Astra sees the matrix and reprograms other AI models directly through their weights

    Researchers demonstrate direct weight manipulation of models to improve performance without retraining.

    The Decoder·2026-11-04 15:44 UTC·paper0.66(n 0.84 · t 0.74)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for GPT-6 Astra sees the matrix and reprograms other AI models directly through their weights
  18. Ai2 and Google collaborate on a new generation of climate models

    Ai2 and Google are developing NeuralGCM+, an open-source model combining physics and AI for climate simulation.
    Ai2 Blog·2026-11-04 08:00 UTC·company announcement0.66(n 0.77 · t 0.86)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Ai2 and Google collaborate on a new generation of climate models
  19. Bots - Granular access controls for the top Personal Agents

    Cloudflare updates AI crawler and agent access policies with granular controls for personal agents.

    Cloudflare AI Changelog·2026-11-04 00:00 UTC·tool0.66(n 0.00 · t 0.78)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Bots - Granular access controls for the top Personal Agents
  20. Anthropic's new prototype proves which model wrote an AI response without exposing its weights

    Anthropic released FlashProve, a cryptographic prototype for verifying model provenance without exposing weights.

    The Decoder·2026-11-04 15:23 UTC·tool0.65(n 0.79 · t 0.74)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Anthropic's new prototype proves which model wrote an AI response without exposing its weights
  21. Load Balancing, Cloudflare Tunnel, Cloudflare Mesh - Steer Cloudflare One users and private networks to the same endpoint with session affinity and hash steering in private load balancers

    Cloudflare private load balancers now support session affinity and hash steering.

    Cloudflare AI Changelog·2026-11-04 00:00 UTC·tool0.65(n 0.84 · t 0.78)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  22. Smart Approvals in Amazon Quick: Human oversight where it matters

    Overview of Smart Approvals in Amazon Quick for human-in-the-loop agent action governance.

    AWS Machine Learning Blog·2026-11-04 16:33 UTC·company announcement0.62(n 0.83 · t 0.80)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  23. Nvidia RTX Spark encrypted firmware slows inference speed to 35% on Linux

    Nvidia RTX Spark firmware encryption causes significant inference performance degradation on Linux.

    Hacker News (AI-filtered)·2026-11-04 08:46 UTC·news0.58(n 0.00 · t 0.65)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  24. OpenAI to acquire Pierre Computer Company, Inc.

    OpenAI acquires Pierre Computer Company to integrate code analysis and development tools.

    OpenAI·2026-11-04 14:30 UTC·company announcement0.57(n 0.79 · t 0.90)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • seen on 2 feeds; not independent verification
    • primary source has high trust weight
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    source trail · 2
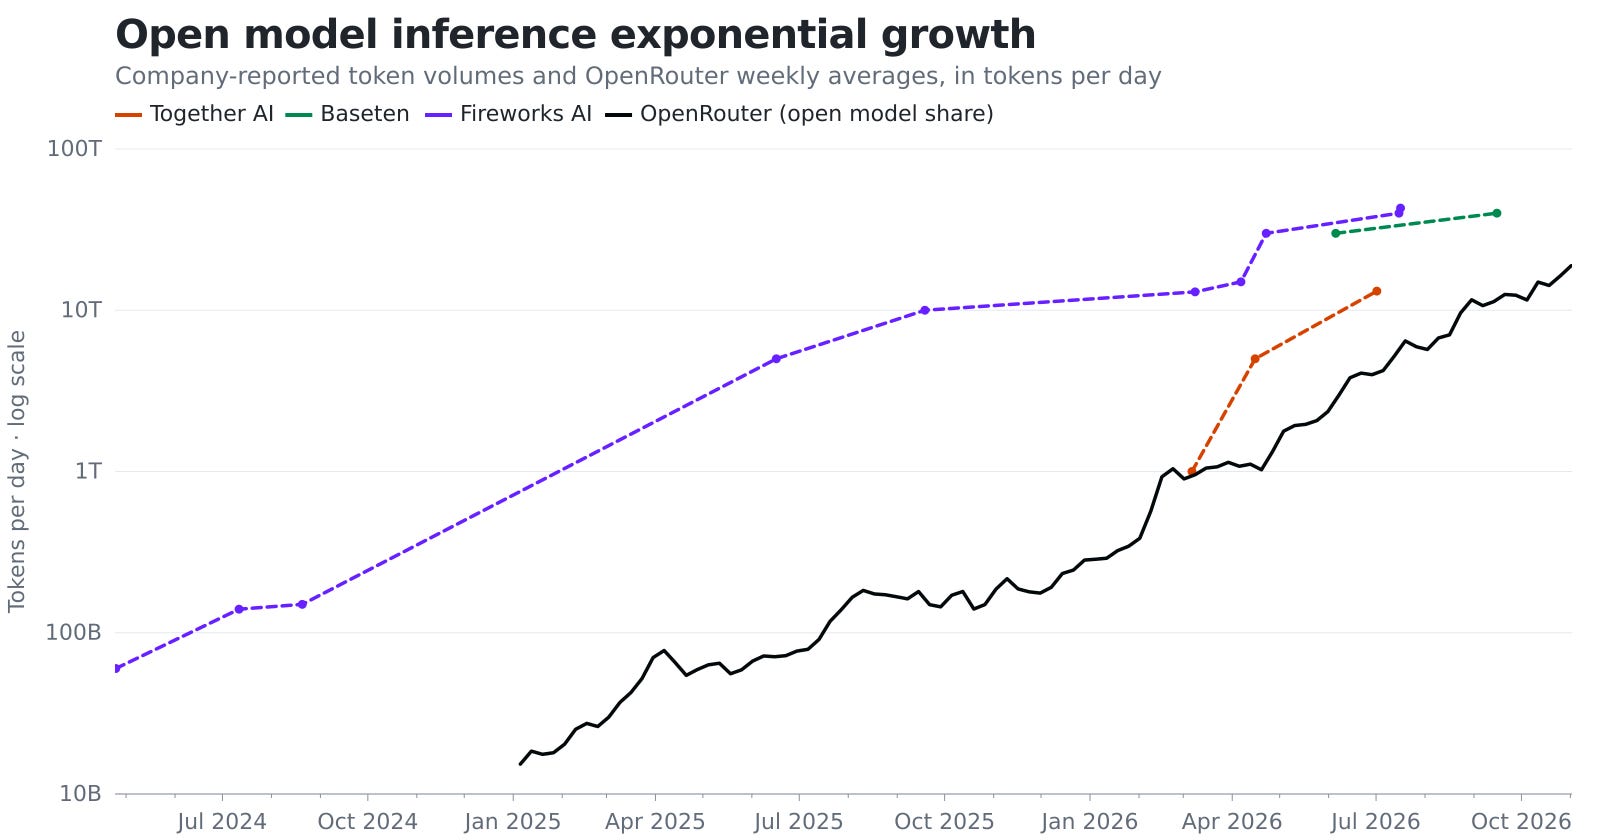
  25. How big is the open model economy today?

    Analysis of the open-source model ecosystem and its current economic landscape.
    Interconnects (Lambert)·2026-11-04 16:35 UTC·news0.57(n 0.82 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • primary source has high trust weight
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for How big is the open model economy today?
  26. Texas was the new epicenter of the AI data center buildout. That might be kaput.

    Political shifts in Texas may impact the state's status as a major hub for AI data center development.

    MIT Technology Review AI·2026-11-04 18:50 UTC·news0.56(n 0.81 · t 0.82)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • fresh within the current refresh window
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  27. Google: We're sharing our framework for building safer and more helpful AI for health.

    Google announces a framework for health AI evaluation, focusing on safety and policy rather than technical methodology.
    Google AI on Keyword·2026-11-04 14:00 UTC·company announcement0.55(n 0.78 · t 0.82)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Google: We're sharing our framework for building safer and more helpful AI for health.
  28. Launch HN: Kino AI (YC S23) – AI media manager and video editor

    Launch of Kino AI, a media management and video editing tool.

    Hacker News (AI-filtered)·2026-11-04 17:31 UTC·tool0.55(n 0.82 · t 0.65)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as useful but lower-confidence signal
    • fresh within the current refresh window
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  29. Rethinking Next-Visit Diagnosis Prediction Beyond Aggregate Metrics: Retrieval--Memory Multi-Agent Adjudication

    Proposes a multi-agent adjudication framework for clinical diagnosis prediction, focusing on evaluation metrics.

    arXiv cs.CL·2026-11-04 05:00 UTC·paper0.53(n 0.00 · t 0.90)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as useful but lower-confidence signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  30. Tell HN: Gemini trains on chat history, even for subscribers (personal accounts)

    User report confirms Gemini personal account chat history is used for model training.

    Hacker News (AI-filtered)·2026-11-04 10:10 UTC·discussion0.49(n 0.00 · t 0.65)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
Yesterday & older(22)
  1. Adversarial Speculative Reasoning Improves Long Horizon Agents

    Argues for using speculative decoding to improve agent reasoning rather than just as a latency optimization.

    Hugging Face Daily Papers·2026-11-03 00:00 UTC·listed 2026-11-04·paper0.83(n 0.77 · t 0.85)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  2. Length Is Cheap, Competition Is Not: Attention Predicts Context Rot in Retrieval

    Demonstrates that retrieval failure in LLMs is driven by attention competition rather than input length.

    Hugging Face Daily Papers·2026-11-03 00:00 UTC·listed 2026-11-04·paper0.83(n 0.78 · t 0.85)
    why surfaced · high
    • specific engineering subject or instructional task in source metadata
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  3. Dory1.0-4B: A Looped Normalized-GPT

    Releases Dory1.0-4B, a 4B parameter latent-recurrent model with elastic depth for variable inference compute budgets.

    Hugging Face Daily Papers·2026-11-02 00:00 UTC·listed 2026-11-04·model release0.73(n 0.85 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  4. datasette-agent 0.5a0

    Datasette-agent update for LLM-driven data analysis workflows.

    Simon Willison·2026-11-03 23:13 UTC·tool0.72(n 0.67 · t 0.90)
    why surfaced · medium
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  5. BEND 2.0: Benchmarking the Capabilities Needed to Design DNA

    Introduces BEND 2.0, a benchmark for evaluating genomic foundation models on DNA sequence design and editing tasks.

    Hugging Face Daily Papers·2026-11-02 19:00 UTC·listed 2026-11-04·paper0.71(n 0.78 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  6. QFabric: Guarded Cross-Domain Task Recovery and Its Limits on a Linux-RTOS Board

    Proposes a framework for task migration between Linux and RTOS domains on embedded boards to manage timing degradation.

    Hugging Face Daily Papers·2026-11-01 00:00 UTC·listed 2026-11-04·paper0.67(n 0.88 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Check the migration or deprecation details against your current integrations.
    How Chronicle selects stories · report a correction
  7. SphereFlow: Missing Modality Imputation via Geometric Transport on Hypersphere

    Introduces SphereFlow for missing modality imputation using geometric transport on a hypersphere.

    Hugging Face Daily Papers·2026-11-03 00:00 UTC·listed 2026-11-04·paper0.67(n 0.86 · t 0.85)
    why surfaced · high
    • high novelty against the 30-day history
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  8. Introducing India-based inference for Kimi K3 on Amazon Bedrock

    Amazon Bedrock adds in-country inference for Kimi K3 in India regions.

    AWS Machine Learning Blog·2026-11-03 16:32 UTC·company announcement0.65(n 0.00 · t 0.80)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  9. Google Launches LiteRT Tensor API for Building, Customizing, and Optimizing ML Models for On-Device

    Google released LiteRT Tensor API, a C++ library for on-device ML model authoring and optimization.
    InfoQ AI/ML/Data·2026-11-03 19:00 UTC·tool0.65(n 0.00 · t 0.78)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Google Launches LiteRT Tensor API for Building, Customizing, and Optimizing ML Models for On-Device
  10. llm 0.37.1

    Update to the LLM CLI tool for interacting with various models.

    Simon Willison·2026-11-03 21:41 UTC·tool0.65(n 0.31 · t 0.90)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  11. moonshotai/Kimi-K3.1-Pro (797 downloads, 469 likes)

    Kimi K3.1 Pro conversational text generation model released in safetensors format.

    Hugging Face trending models·2026-11-02 04:13 UTC·listed 2026-11-04·model release0.65(n 0.75 · t 0.58)
    why surfaced · medium
    • meaningfully different from recent coverage
    • classified as concrete builder or research signal
    • trending observed 2026-11-04; publication date preserved
    • fresh within the current refresh window
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  12. Rapid LLM development is outrunning the research meant to explain it, study finds

    Stanford study finds 44 percent of cited LLM research claims are expired, with an average lifespan of 15.7 months.

    The Decoder·2026-11-03 19:41 UTC·paper0.64(n 0.00 · t 0.74)
    why surfaced · familiar
    • specific engineering subject or instructional task in source metadata
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
    Thumbnail for Rapid LLM development is outrunning the research meant to explain it, study finds
  13. When Fine-Grained Credit Assignment Helps and Hurts: Multimodal Agentic Reinforcement Learning through Video Editing

    Investigates the impact of fine-grained credit assignment in multimodal RL using video editing tasks.

    Hugging Face Daily Papers·2026-10-26 00:00 UTC·listed 2026-11-04·paper0.59(n 0.74 · t 0.85)
    why surfaced · medium
    • meaningfully different from recent coverage
    • classified as useful but lower-confidence signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  14. Think Less, Locally: Local Preference Learning for Reasoning Compression

    Introduces local preference learning to compress reasoning chains and reduce inference costs in large models.

    Hugging Face Daily Papers·2026-11-03 00:00 UTC·listed 2026-11-04·paper0.57(n 0.00 · t 0.85)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • source-native discussion or engagement is unusually high
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  15. Every Token Needs Its Own Teacher: Multi-teacher Adaptive On-policy Self-distillation

    Proposes multi-teacher adaptive on-policy self-distillation to improve LLM post-training by dynamically conditioning teachers.

    Hugging Face Daily Papers·2026-10-29 00:00 UTC·listed 2026-11-04·paper0.56(n 0.00 · t 0.85)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  16. You don't need long context

    Demonstrates that frequent context compaction maintains performance on long-horizon tasks while significantly reducing inference costs.

    Hugging Face Daily Papers·2026-11-03 00:00 UTC·listed 2026-11-04·paper0.56(n 0.00 · t 0.85)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  17. Muon Makes the First Mixture-of-Experts Layer Harder to Balance

    Analysis of Muon optimizer impact on MoE router training and load balancing in small-scale language models.

    Hugging Face Daily Papers·2026-10-27 00:00 UTC·listed 2026-11-04·paper0.56(n 0.00 · t 0.85)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • listed on Daily Papers 2026-11-04; publication date preserved
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  18. Bring structured and unstructured data together with Amazon Quick

    Walkthrough on connecting S3 data to Amazon Quick to build a RAG-based chat agent for business data.

    AWS Machine Learning Blog·2026-11-03 16:49 UTC·tutorial0.53(n 0.00 · t 0.80)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    • Inspect the evaluation setup, data and baselines before applying the reported results.
    How Chronicle selects stories · report a correction
  19. ServiceNow on-behalf-of token exchange with Bedrock AgentCore Gateway

    Technical guide for configuring OBO token exchange between Bedrock AgentCore Gateway and Microsoft Entra ID.

    AWS Machine Learning Blog·2026-11-03 16:47 UTC·tutorial0.53(n 0.00 · t 0.80)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
  20. Qwen 3.8 27B on my laptop can interpret model weights, too

    Demonstration of using Qwen 3.8 27B to interpret and analyze model weight structures.

    Simon Willison·2026-11-03 16:29 UTC·tutorial0.49(n 0.00 · t 0.90)
    why surfaced · familiar
    • kept for context despite familiar coverage
    • classified as concrete builder or research signal
    • primary source has high trust weight
    • Assessment: llm. Model assessment from source metadata; not independently verified
    How Chronicle selects stories · report a correction
You're caught upNext refresh follows the public schedule.

Previous editions

Same signal-first ranking, earlier dates.

Open archive